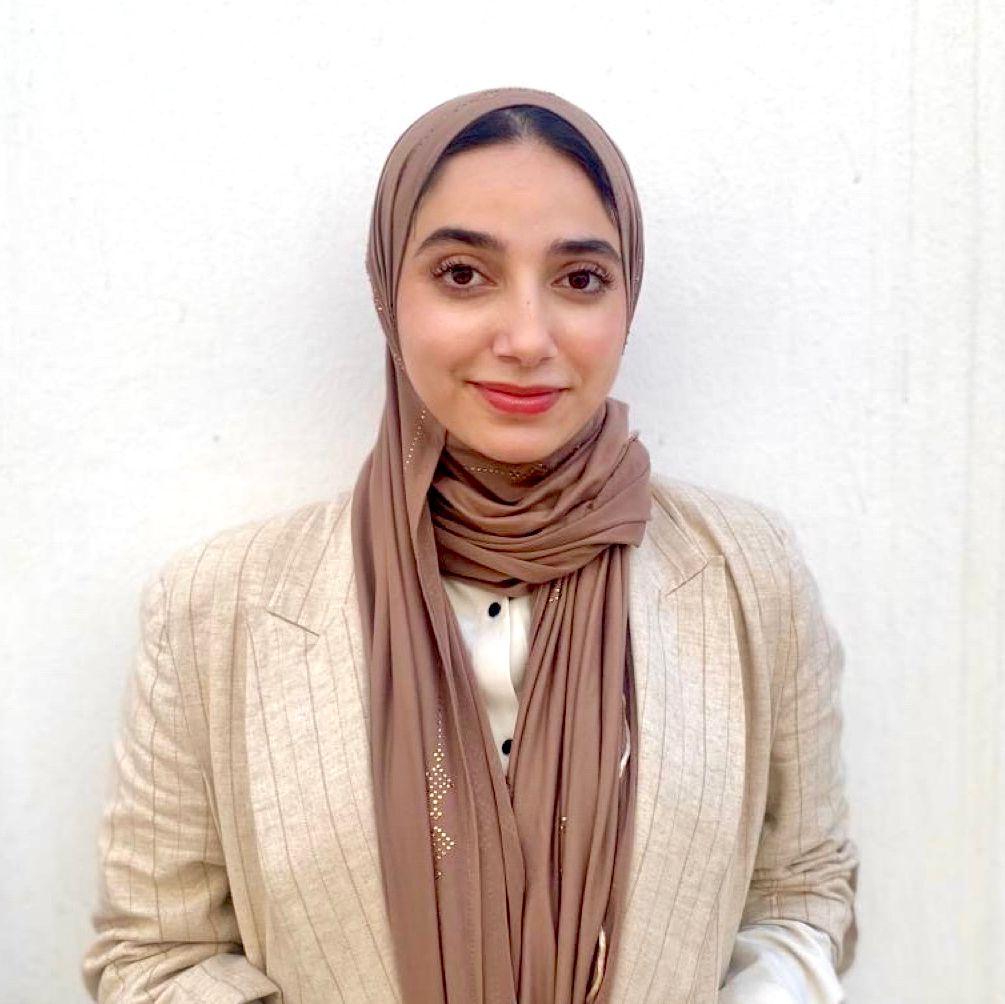
Generative AI engineer · Available now

GenAI that earns its budget back

Generative AI Engineer. I take LLM systems from prototype to production and prove they paid off. At a Dutch insurer I shipped a customer-facing assistant handling ~8K interactions a month at 83% end-to-end resolution, and an email agent processing ~2K emails a month at 70% — both running on a KPI dashboard I built so the numbers survive scrutiny.

Samiha El Mansouri

— Samiha El Mansouri, Morocco

10,000

Customer interactions handled per month in production

80%

Resolved end to end, no human agent involved

4 sec

Average response time

83%

Positive customer feedback

Selected work

Three production systems.

What constrained them, and how I proved they worked.

01 — Ominimo · 2025–26

Multi agent assistant that answers and acts on live policies for a Dutch insurer

Answering a question wrong costs you a review. Changing the wrong policy costs you a regulator. This assistant does both: a QA layer over policy documents, and a set of agents that execute real account changes name, email, phone, primary and additional coverage, cancellations with intent classification, guardrails and confirmation before anything is written. Anything outside its competence escalates to a human by design.

8,000

interactions / month

80%

end-to-end resolution

83%

positive feedback

02 — Ominimo · 2026

Email automation that respects the SLA

The inbox was the bottleneck. Built an LLM pipeline that reads, classifies and answers incoming mail, and just as important knows which 30% to hand to a human immediately rather than guess.

2,000

emails / month

70%

fully automated

95%

inside 24h SLA

03 — Ominimo · 2025–26

The dashboard that made the AI accountable

Most GenAI projects stall because nobody can answer "is it working?" I designed the observability layer the team runs on automation rate, intent accuracy, escalation rate, resolution and latency, tracked continuously rather than sampled after a complaint.

5 KPIs

monitored in production

98%

context accuracy on an earlier RAG build

How I work

Three rules I do not bend.

01

Measure before you scale

An eval set and a KPI dashboard come first. Without them you are shipping opinions.

02

Escalation is a feature

A system that knows its limits beats one that answers everything confidently and wrongly.

03

Report in business terms

Resolution rate and cost per ticket, not perplexity. Your team should understand the number.

Contact

Sitting on a support queue that keeps growing?

Tell me what your team spends its day answering. I will tell you honestly how much of it can be automated — and how much of it should not be.